A working demo can hide serious production risks. This service stabilizes projects built with Lovable, Bolt, Bubble, Retool, FlutterFlow, Replit, Cursor, or similar no-code, low-code, or AI coding tools that prove the idea but break under real user behavior, production data, or live traffic.

What is the difference between a fragile prototype and a validated PoC?
A fragile prototype may demonstrate the idea, but a real PoC tests whether the critical path remains stable under realistic user, data, traffic, and deployment conditions.
| Comparison point | Fragile prototype or AI demo | Validated PoC |
| Production readiness | Works in a controlled demo but may fail with real users, data, or traffic | Validates the highest-risk path under realistic production assumptions |
| Performance and scale | Slows down, times out, or becomes unstable as workload increases | Measures latency, throughput, error rates, and resource use |
| Root-cause visibility | Shows recurring symptoms without identifying the actual bottleneck | Traces failures across code, infrastructure, data, integrations, and model calls |
| AI, data, and integrations | Model behavior, queues, APIs, or data flows may become unreliable under pressure | Tests the selected AI or data flow, including limits, errors, fallbacks, and edge cases |
| Observability and recovery | Incomplete logs and alerts make incidents difficult to reproduce or resolve | Defines the metrics, traces, alerts, rollback, and recovery controls needed for launch |
| Security and deployment | Relies on temporary access rules, manual releases, or inconsistent environments | Reviews security gaps and prepares a controlled deployment path |
| Engineering decision | No clear evidence on whether the current foundation can support the next stage | Provides evidence to fix, redesign, rebuild, or stop extending the current prototype |
| Ownership and handoff | Technical knowledge remains fragmented across tools, vendors, and individuals | Delivers documented findings, priorities, risks, and a clear production roadmap |
Prototypes are built to prove an idea, not to survive production. Moving from a demo to a live system introduces concurrency, partial failures, security controls, and real data volumes — conditions the prototype was never designed for — which quickly drive up operational complexity and cloud costs.
Operational controls arrive too late
Authentication, access rules, secrets, audit trails, monitoring, backups, and recovery are often absent in demo builds. Each one needs explicit controls in place before customer data enters the system.
IT experts are ready to start rescuing failing software projects for you
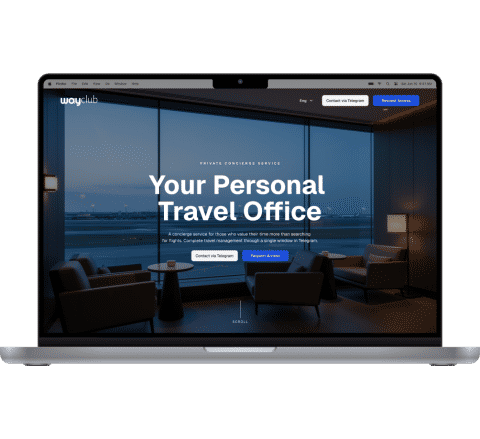
From fragmented travel requests to an AI-powered concierge platform
Geniusee partnered with a small travel company to develop an AI-powered concierge platform that integrates travel assistance and service management into a single digital environment. The MVP combines an AI-powered chatbot for travelers with an administrative platform for managing its content, users, data, and operations.
Case details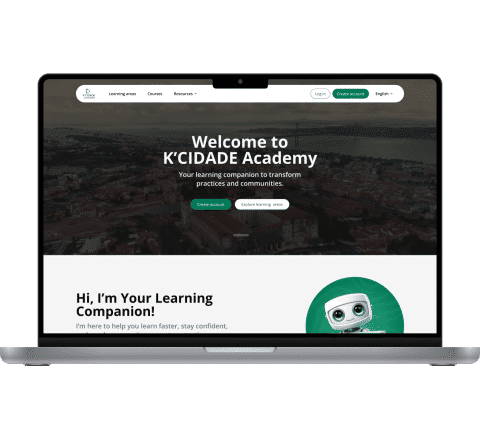
K’CIDADE Academy: How we built an AI-powered learning platform for AKF Portugal
K'CIDADE Academy is AKF Portugal's professional learning platform for civil society organizations, educators, and community leaders. Built on adaptive learning pathways, an AI virtual tutor, and a gamified progress system, it delivers personalized training to professionals working across social inclusion, education, and community development.
Case details

Scaling Edge AI & computer vision: QuantumEye real-time surveillance platform
Geniusee helped the QuantumEye AI platform that upgrades legacy CCTV with real-time detection, instant incident notifications, and decision-ready analytics.
Case details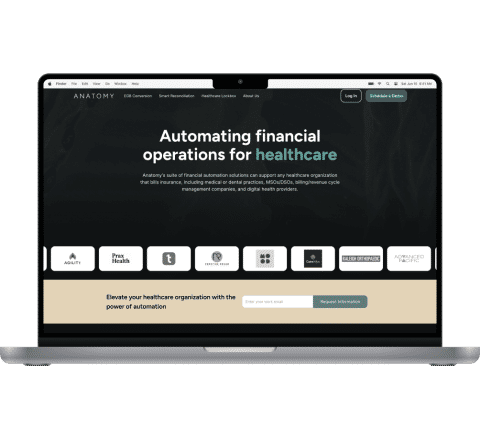
Anatomy Financial: Automated financial management software for healthcare
Anatomy introduces an innovative solution designed to automate document processing, compare various documents and banking transactions, and handle the intricacies of physical check processing. By conducting a thorough analysis, the system identifies discrepancies between the declared prices of medical procedures and the actual amounts received by the clinic.
Case details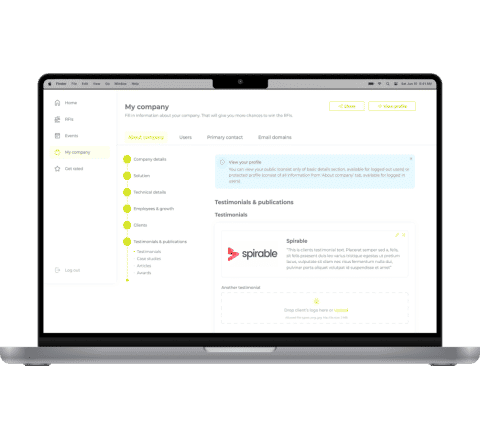
Validify – Retail vendor management platform
See how Geniusee built Validify’s scalable vendor management platform with advanced UX, data architecture, and automated RFI workflows.
Case details
 Martech
Compose AI: Advanced content writing solution
We partnered with Compose AI to enhance their AI-powered writing platform through cloud migration, UX improvements, seamless integrations, and scalable feature development, upporting their growth from YC-backed startup to a widely adopted productivity tool.
Case detailsWhat production risks can a prototype rescue PoC help you reduce?

“A prototype rescue PoC helps you identify the weakest production path before customers expose it.
By measuring the real bottleneck, we can determine whether your current product prototype should be fixed, redesigned, partially rebuilt, or no longer extended at all.
This gives your team evidence that helps reduce latency, downtime, security gaps, and cloud-cost risks while making architecture decisions based on tested conditions rather than bare assumptions.”
Taras Tymoshchuk
CEO, Founder



Triage the production symptoms
We identify what fails, when it fails, and why it matters to the business.
✔️ Affected users, workflows, and environments
✔️ Traffic, data, latency, cost, and reliability targets
✔️ Known incidents, launch constraints, and production risks
Find the root cause
The team traces the failure across code, data, infrastructure, integrations, and model behavior.
✔️ Architecture and critical code paths
✔️ Database, API, queue, and model dependencies
✔️ Logs, metrics, traces, alerts, and missing evidence
Validate under realistic conditions
The corrected path is tested against agreed usage assumptions rather than a simple demo scenario.
✔️ Expected concurrency, data, or workflow volume
✔️ Latency, error rate, model behavior, and recovery
✔️ Deployment, rollback, and handoff assumptions
Prepare the production plan
We translate the findings into an actionable fix-and-ship plan.
✔️ Target architecture and deployment path
✔️ SLOs, security, observability, and capacity plan
✔️ Backlog, priorities, owners, risks, and estimates
- Onboarding and KYC flows that break under document volume or verification queues
- Payment prototypes that fail under concurrent users or partial transaction failures
- Lending workflows that need proper audit trails and reliable data state across stages
- Approval and compliance tools with fragile integrations or inconsistent access control
- Trading dashboards that slow down or produce inconsistent output as data volume grows
- Reporting systems that lose accuracy or performance under real user and data load
- Learning management prototypes that struggle with concurrent learner sessions at scale
- AI tutoring flows with unstable model output or inconsistent scoring under real usage
- Video and content delivery systems that degrade as enrolled users and media files grow
- Enrollment and certification workflows that depend on manual steps or fragile integrations
- Assessment tools that expose data integrity issues under realistic submission volume
- Progress tracking systems where background jobs or sync logic becomes unreliable at scale
- Catalog and search prototypes that slow down as SKU volume and concurrent queries grow
- Checkout flows that expose payment reliability or data integrity issues under real load
- Order management tools where event-driven logic becomes unstable at transaction volume
- Computer vision workflows for shelf or inventory automation that need validated thresholds
- Vendor and marketplace tools with unreliable background jobs or fragile pricing logic
- Recommendation and personalization flows with inconsistent output under production data
- Property search platforms that lose performance as inventory and user activity scale up
- Document review workflows built on fragile automation that fails under real data conditions
- Lead qualification flows that rely on manual handoffs or untracked API dependencies
- CRM integrations with inconsistent environments or missing error handling across stages
- Permitting tools that need proper audit trails and reliable external service integrations
- Listing and content pipelines where sync failures or data gaps appear only under live load


What kinds of prototypes does this service apply to?
This service is designed for products built with no-code, low-code, or AI coding tools such as Lovable, Bolt, Bubble, Retool, FlutterFlow, Replit, or Cursor. If the product proved the concept but now fails under real users, production data, or growing traffic, it is a strong candidate for a prototype rescue PoC.
How is a prototype rescue PoC different from a standard technical audit?
A technical audit identifies problems and documents them. A prototype rescue PoC goes further: it traces the root cause of the specific failure, addresses the highest-risk bottleneck, validates the fix under realistic conditions, and delivers a production roadmap alongside the findings. The output is evidence you can act on, not just a report.
How long does the process take?
The timeline depends on the complexity of the failing path, the number of integrations involved, and the scope of the remediation. A focused triage and fix typically takes between 2 and 5 weeks. If the bottleneck involves complex infrastructure, AI pipelines, or multiple integrated systems, the engagement may extend to 6 to 8 weeks. Geniusee will give you a more specific estimate after the initial triage call.
Do you rewrite the entire prototype or only the failing part?
The PoC targets the highest-risk component, not the entire codebase. Stable, usable components are kept as they are. The goal is to apply the smallest meaningful fix that provides clear production evidence, rather than committing to a full rebuild before it is justified.
What do we receive at the end of the engagement?
You receive a validated fix for the identified bottleneck, before-and-after performance findings, documented root cause analysis, and a production roadmap covering architecture, service-level objectives, security, observability, prioritized backlog, team recommendations, and a realistic timeline and cost estimate for the next stage.
Can Geniusee help us decide whether to fix, rebuild, or stop extending the prototype?
Yes, and that decision is a core output of the process. Once the bottleneck is measured and tested, you have the engineering evidence to determine whether the current foundation is worth continuing, requires a partial rebuild, needs a complete re-architecture, or should not be extended further. The PoC is structured to produce that decision, not to delay it.
What involvement does our team need to provide during the engagement?
Your team needs to be available for the initial triage session, to provide access to the relevant environments, codebases, logs, and integrations, and to review findings at key stages. Geniusee manages the technical execution. The level of day-to-day involvement from your side is usually low, but access and timely decisions on scope or priorities will affect the pace of the work.
How do you handle security and data access during the PoC?
Geniusee is ISO 27001-certified and applies controlled access practices to every engagement. We work with your team to define which environments and data are accessible, use the minimum required access for the work, and document any security gaps identified during the assessment as part of the output.
Can the PoC lead directly into a full production build?
Yes. If the findings support continued development, Geniusee can transition to a full product engineering engagement using the validated architecture, roadmap, and backlog developed during the PoC. The rescue engagement is designed to give your team a clean, documented foundation to build on, whether with Geniusee or your own engineering team.
What if the problem is in the AI layer rather than the infrastructure?
AI-specific failures such as inconsistent model output, rising inference costs, retrieval gaps, context limit issues, or unreliable orchestration are within scope. The PoC can target the model layer, the prompt logic, the RAG pipeline, the data flow, or the integration between AI components and the broader application, depending on where the root cause sits.