About the client
Planck Technologies is a Norwegian deep-tech company based in Lysaker, near Oslo. The company develops AI technology for materials discovery, with a focus on porous materials used in applications such as CO₂ capture, biogas upgrading, hydrogen and methane storage, and space technologies.
Its platform screens more than 100,000 porous materials and evaluates how they could perform within real industrial processes. Planck combines computational chemistry, machine learning, and process engineering to narrow a large materials space down to candidates worth further investigation.
Business context
Planck Technologies depends on large volumes of high-quality scientific data to evaluate materials and identify candidates for industrial applications.
Much of this information lives across thousands of scientific papers rather than in a single structured database. Material properties appear in narrative text and tables, while researchers may describe the same compound using different names, aliases, formulas, units, and reporting formats.
Collecting and organizing this information manually required researchers to review publications individually and transfer relevant values into spreadsheets. This slowed dataset growth, introduced opportunities for inconsistencies, and made direct comparison between papers difficult.
Planck needed a repeatable way to convert scientific literature into structured, searchable evidence while retaining the context behind every extracted value. The company also needed an AI layer that could search this evidence, validate relevant compounds, and provide researchers with verifiable answers based on the underlying publications.
Scientific data distributed across thousands of papers, tables, and different publication formats
Inconsistent compound names, aliases, formulas, units, and measurement conventions
Complex PDF layouts and scientific tables that standard document parsers could not process reliably
Need to preserve the original scientific context and source location behind every extracted property
AI research results requiring chemical validation and duplicate filtering
High-volume document processing that had to remain manageable in both processing time and cloud cost
Backend
AI & NLP
Infrastructure
Solutions we implemented
The project followed Agile with Scrum practices, using 2-week sprints, sprint planning, working demos, and a Jira backlog. Planck’s chemists regularly reviewed extracted data, allowing the team to convert domain feedback into updated rules and validation cases.
Automated scientific literature collection
Our team developed a pipeline that identifies and downloads publications from open-access sources in PDF and HTML formats.
The collection process detects duplicate publications and supports incremental runs, allowing Planck to add newly published research without reprocessing the same documents. The resulting workflow continuously expands the scientific corpus while keeping previously processed publications under control.
Context-preserving scientific data extraction
The pipeline reads narrative text and tables to identify compounds, materials, and reported properties. Each extracted record retains the context in which the value appeared, including the original alias, raw value, and unit, relevant experimental conditions, and its location within the paper. Scientists can trace structured data back to the original publication and verify how a value was reported.
Domain-specific normalization and quality control
A normalization layer maps aliases and alternative compound names to canonical entities, standardizes chemical formulas, and converts measurement units into comparable formats. Quality rules and confidence checks identify incomplete or ambiguous records, including missing measurement conditions or uncertain entity matches. Records that require scientific judgment can be reviewed before being entered into the comparable dataset.
Source-backed AI research
For generation, the system runs an AI agent to search over-indexed and structured scientific papers, validates every result chemically, and filters out duplicates and compounds. The agent returns relevant materials together with scientifically meaningful details such as reported properties, measurement conditions, selectivity, and aliases. Supporting papers remain connected to the answer, allowing researchers to inspect the evidence behind the results.
Searchable scientific evidence layer
Accepted and normalized records enter a structured evidence index with their source provenance preserved. This gives the AI agent a quality-controlled dataset to search rather than relying on unstructured publication text alone. Paper URLs and precise references to pages, tables, or sections remain connected throughout the workflow.
Cloud infrastructure and pipeline operations
We set up the AWS environment required to run the workload, including containerized services, infrastructure-as-code, automated deployment, centralized logging, and monitoring. Heavy processing stages can scale up when large publication batches or model workloads run, and then reduce capacity afterward. Batching, parallel processing, caching, and incremental updates further reduce unnecessary processing.
Source-backed scientific generation
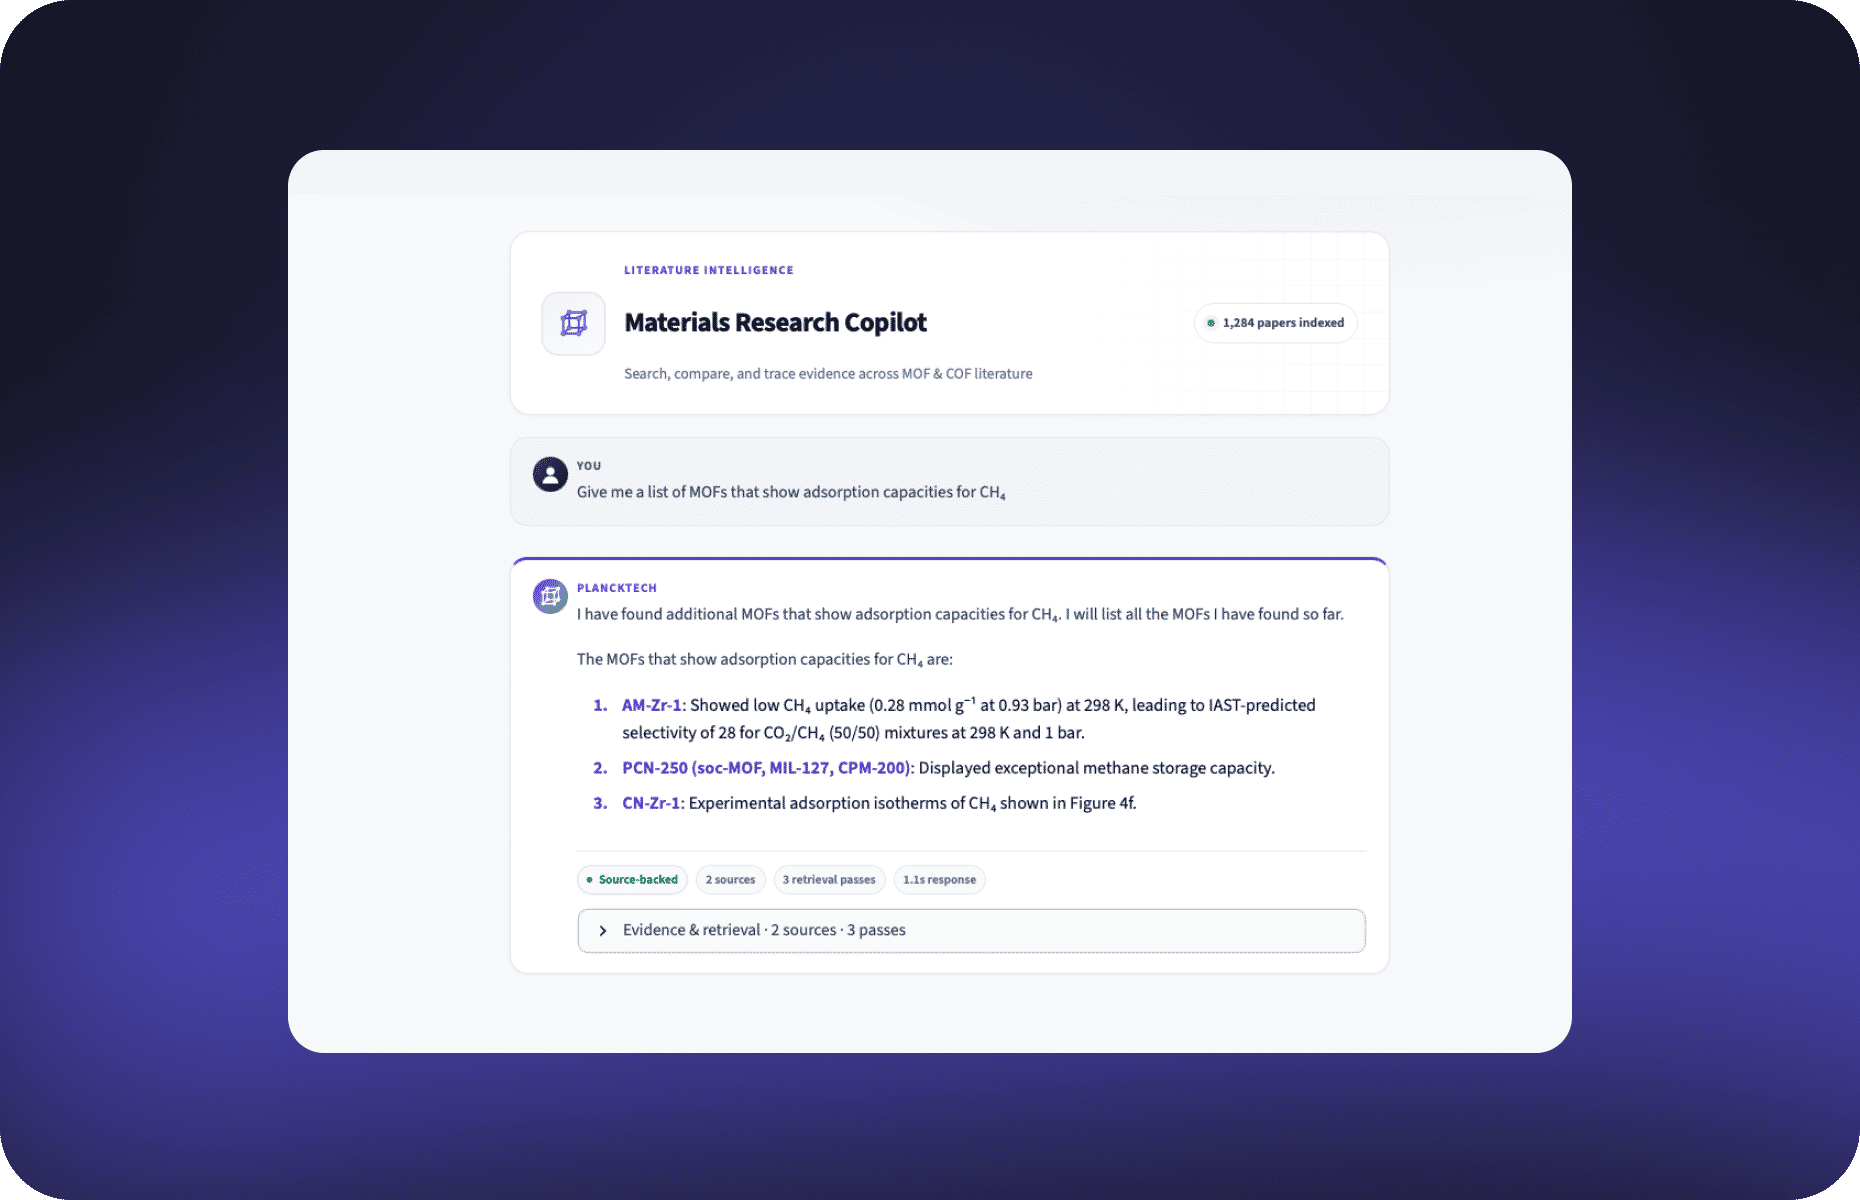
Completed source-backed research answer
A scientist asks for MOFs with specific/needed properties, and the AI agent returns a concise list of relevant frameworks with key details such as uptake, pressure, temperature, selectivity, and aliases. The agent searches indexed, structured papers, validates chemical results, and removes duplicates. Source status, source count, retrieval passes, and response time remain visible, with supporting evidence available for review.
Business value: Researchers receive useful answers quickly without losing the ability to verify the underlying science.
Automated literature collection pipeline
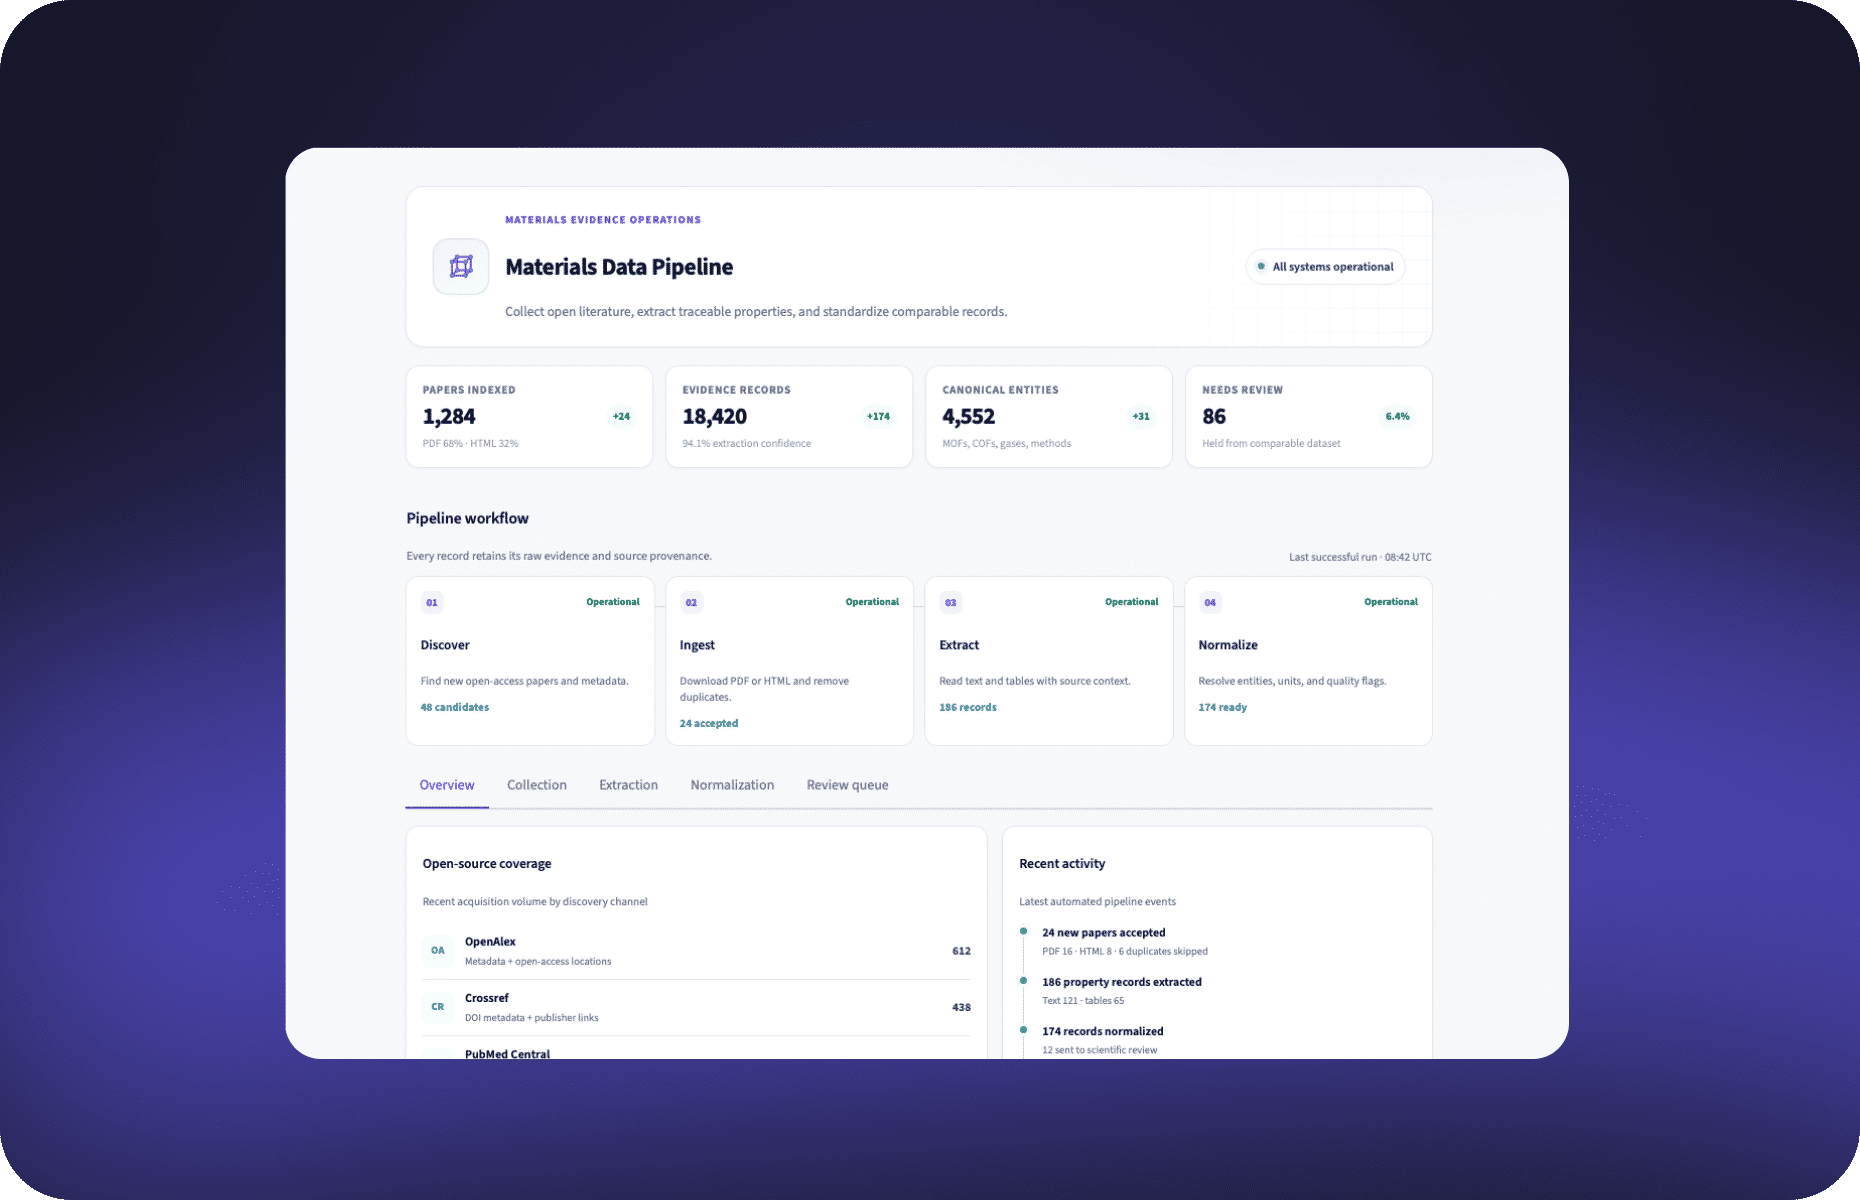
Automated materials data pipeline
The operations dashboard covers the flow from publication discovery to analysis-ready data. The system finds open-source papers, downloads PDF and HTML content, removes duplicates, extracts scientific evidence, and normalizes accepted records. It also tracks corpus size, extracted records, canonical entities, review workload, source coverage, and recent activity.
Business value: Scientific datasets stay current through a repeatable, observable collection process rather than manual paper gathering.
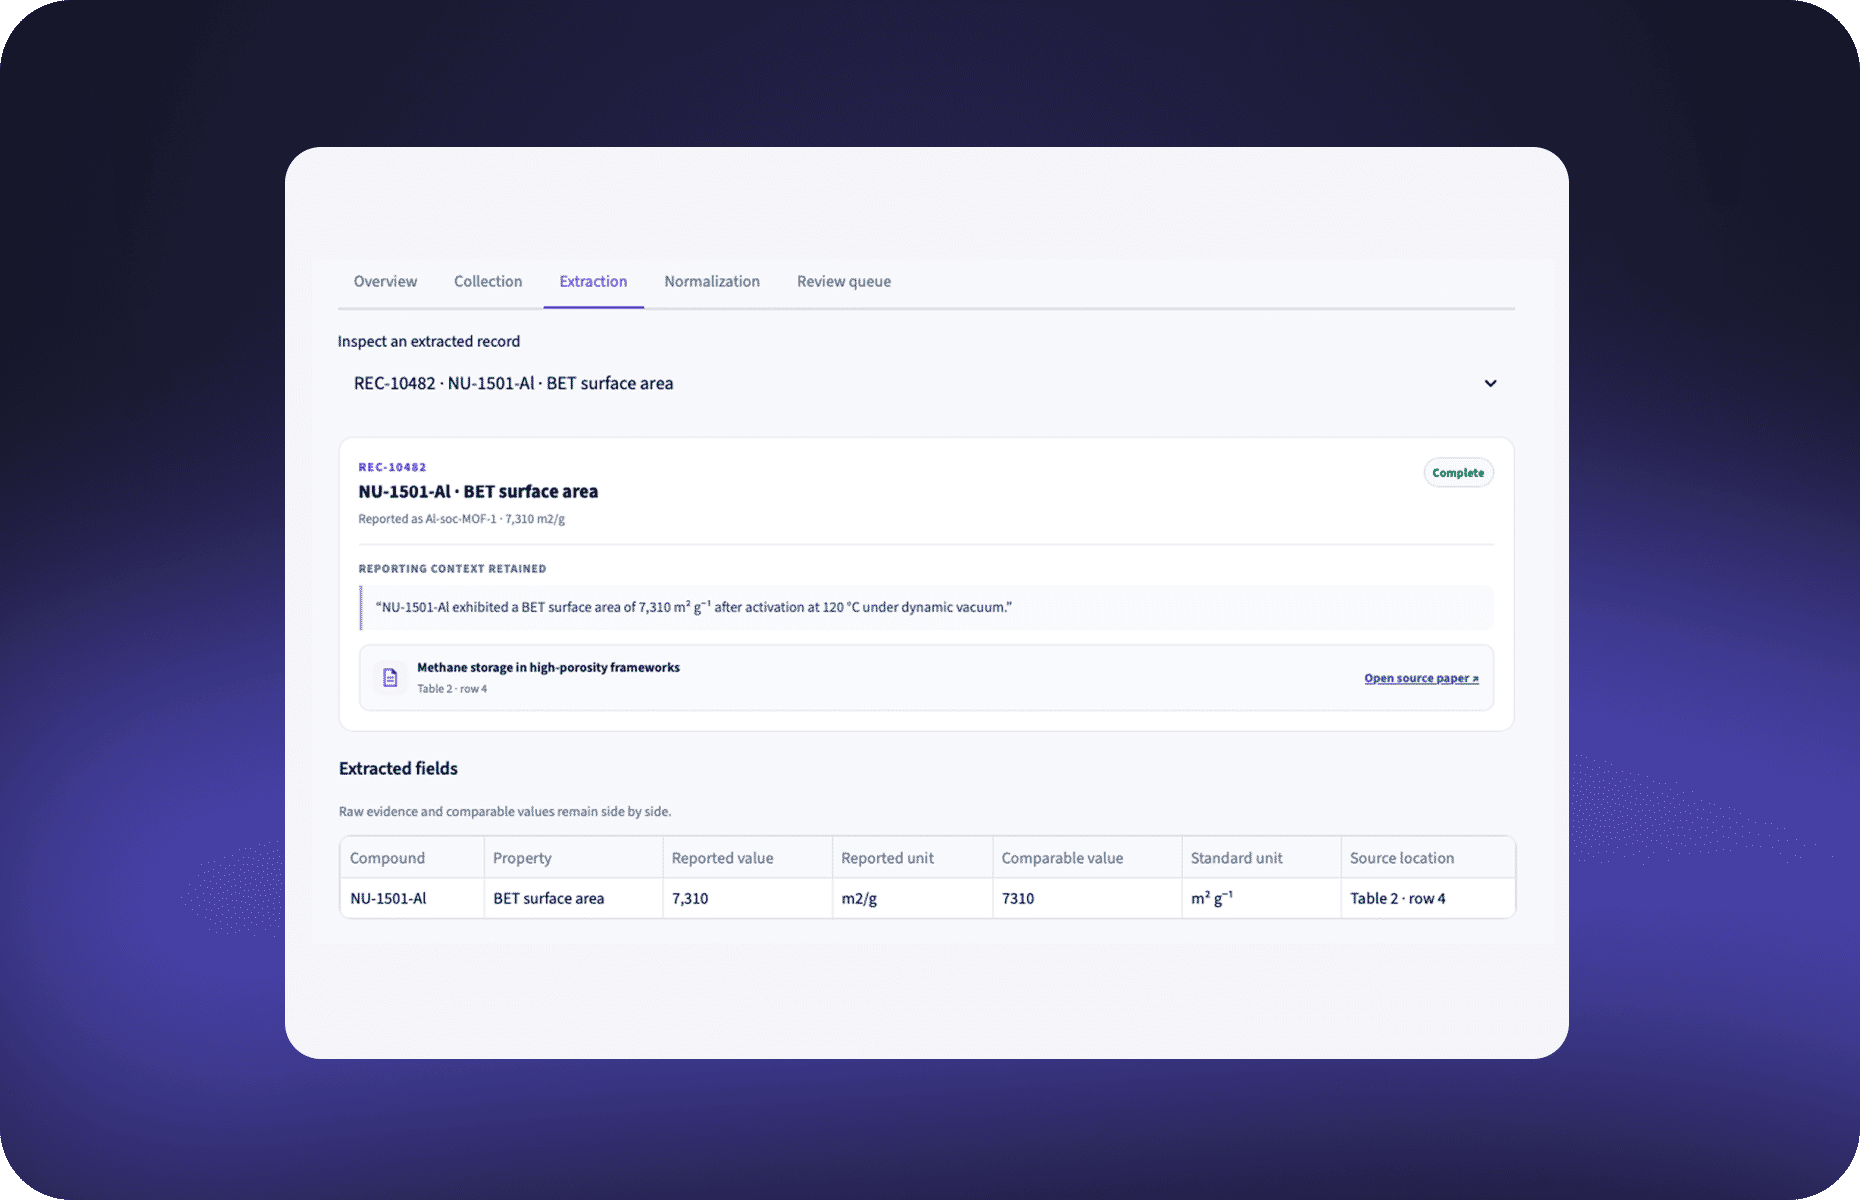
Context-preserving property extraction
Scientific property extraction with source provenance
The system reads narrative text and tables, identifies compounds and properties, and preserves the context in which each value was reported. Records include the original alias, raw value, and unit, activation conditions, table location, normalized value, and a direct link to the source evidence.
Business value: Extracted data remains scientifically auditable and can be trusted in downstream analysis.
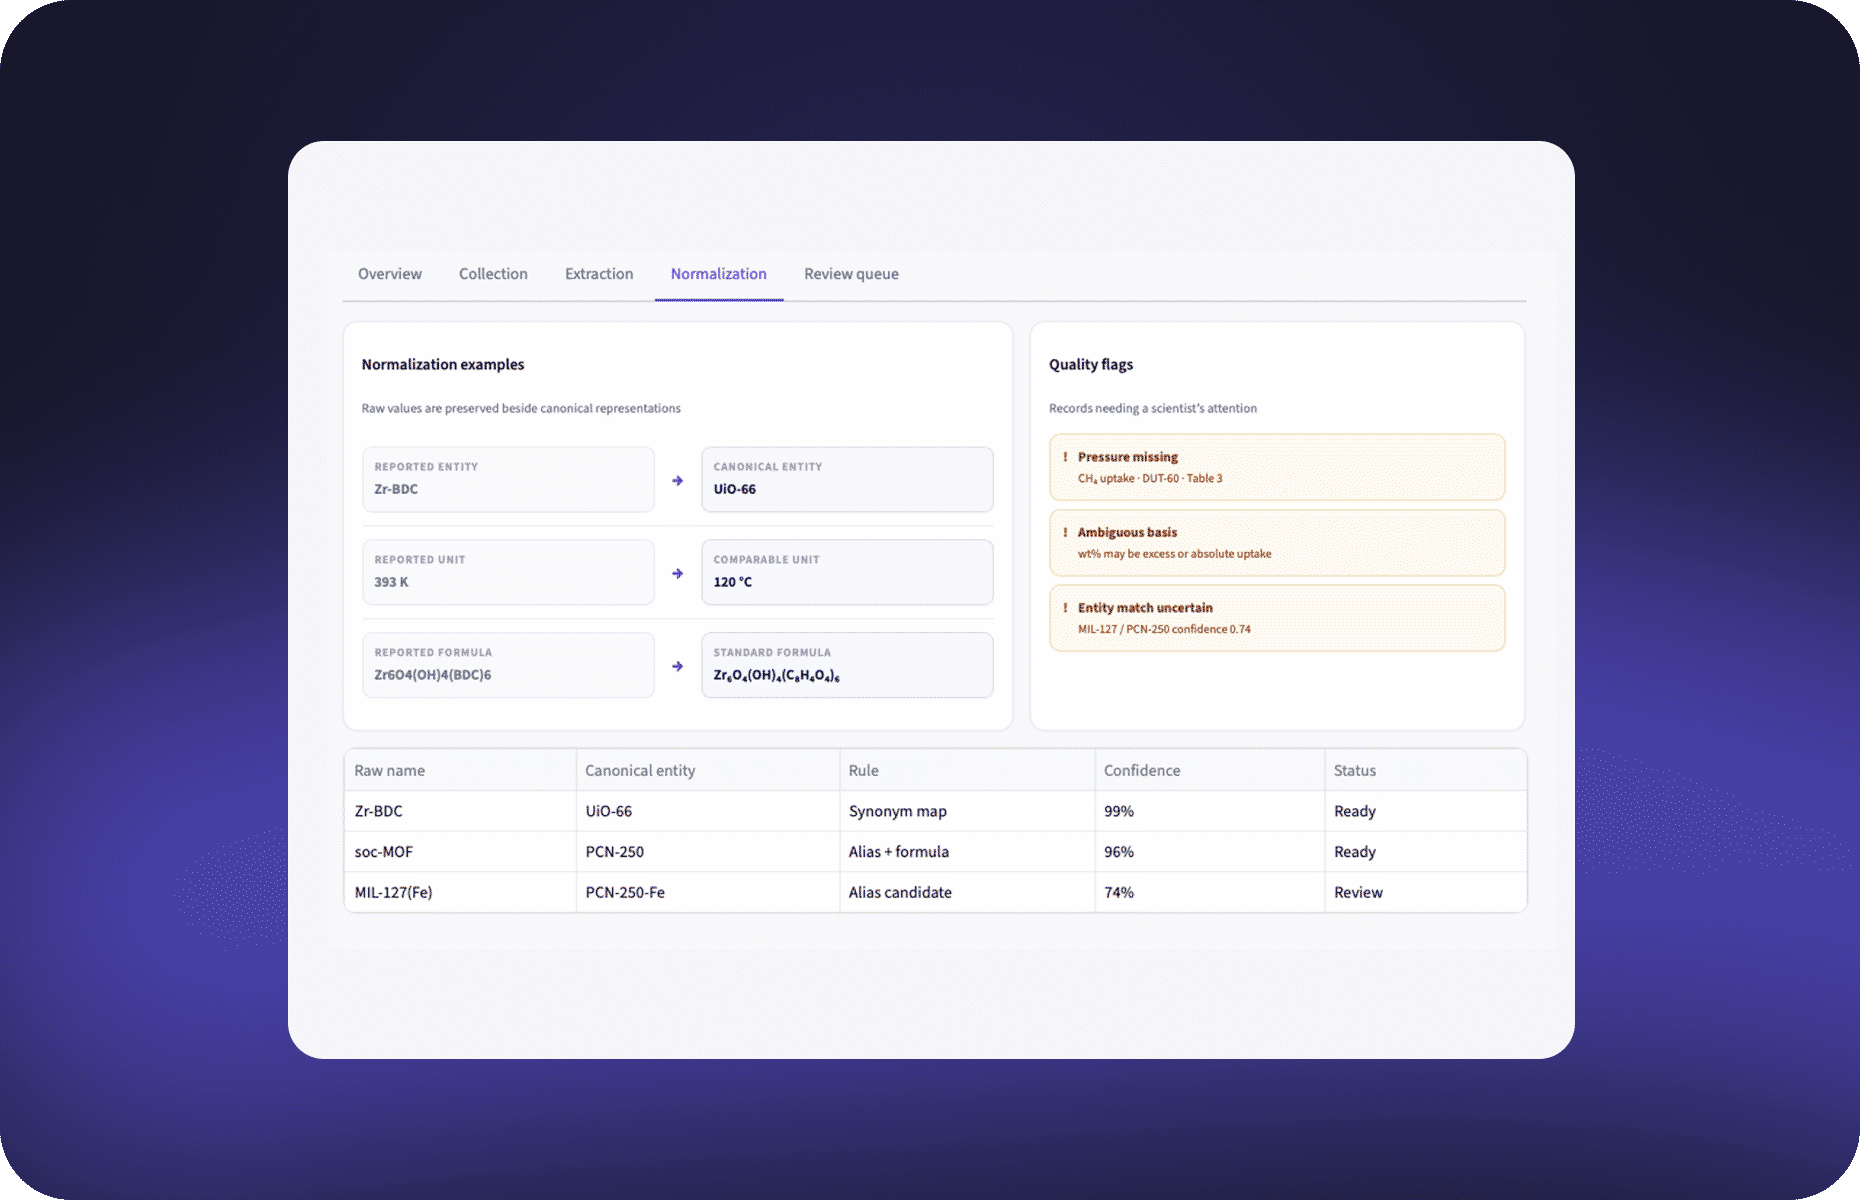
Scientific quality control
Normalization and quality-control workspace
The workspace maps compound names and aliases to canonical entities, standardizes formulas, and converts units into comparable formats. Confidence scores and quality rules flag missing conditions, ambiguous measurements, and uncertain entity matches for scientific review.
Business value: Values reported differently across papers become consistently comparable while uncertain records remain visible and controlled.
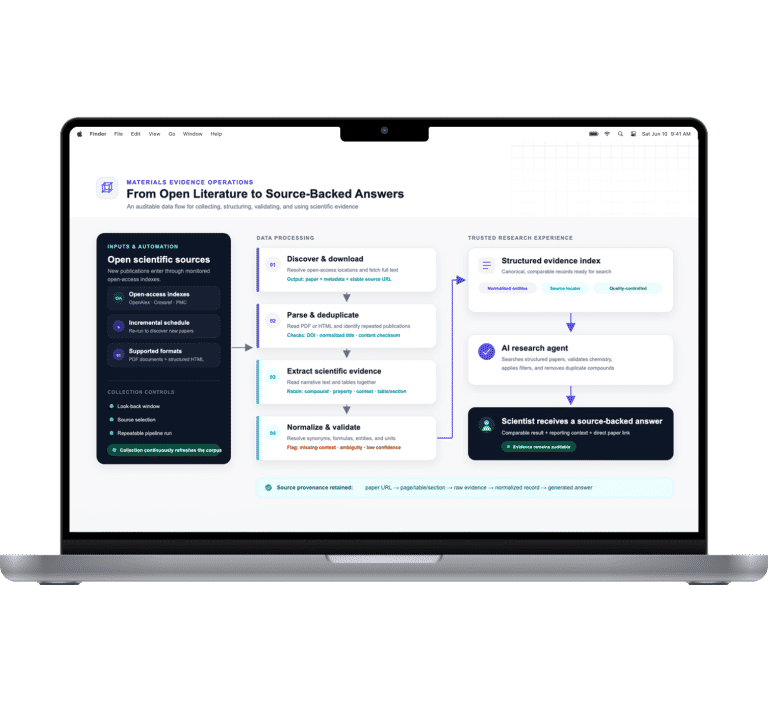
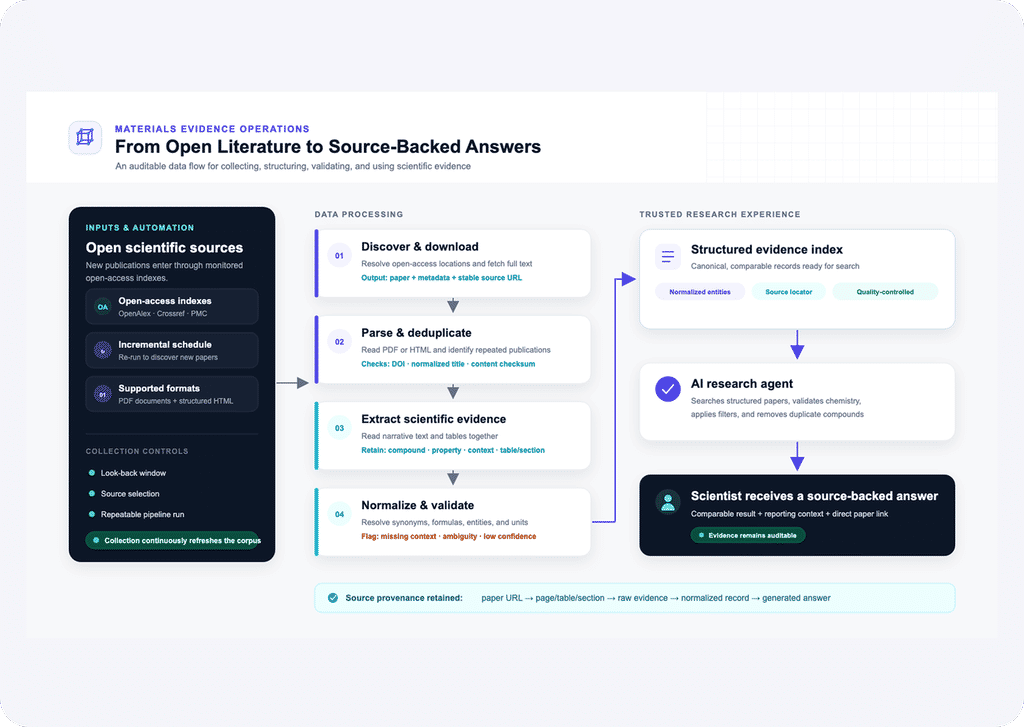
Plancktech data processing and research workflow
The diagram shows how Plancktech turns open scientific literature into auditable research answers. Papers are collected incrementally, deduplicated, and processed to extract compounds, properties, reporting context, and source locations. The data is then normalized, quality-checked, and added to a structured evidence index. The AI research agent searches for this evidence, applies chemical validation and filtering, removes duplicates, and returns source-backed answers, preserving publication references throughout the workflow.
Capability achieved: End-to-end scientific data processing with incremental collection, deduplication, contextual extraction, normalization, quality control, and verifiable AI generation.
The project gave Planck Technologies a structured scientific data layer that supports research workflows and AI-assisted materials discovery.
✅ 10,000 scientific papers processed
The automated pipeline has processed 10,000 scientific papers, replacing a publication-by-publication collection workflow with a repeatable data ingestion and processing workflow.
✅ 10,000 compounds extracted and normalized
The system has extracted and normalized 10,000 compounds, bringing differently reported names, formulas, and units into a comparable data structure.
✅ Searchable scientific evidence instead of manual spreadsheets
Planck’s team can query structured materials data rather than manually reviewing individual papers and copying values into spreadsheets. Researchers can also return from a normalized record to the supporting publication when scientific verification is needed.
✅ Comparable data across publications
Normalization makes values reported under different aliases, formulas, and units easier to compare across papers, while uncertain records remain available for scientific review.
✅ Source-backed AI research
The AI agent searches indexed, structured scientific evidence, applies chemical validation, removes duplicate results, and returns relevant findings along with supporting publications.
Researchers receive concise answers while retaining the ability to inspect the scientific evidence behind them. This creates a closed workflow from publication collection and extraction through normalization and AI-assisted research.
Scientific documents varied significantly in structure
Tables, formulas, and publication layouts frequently behaved differently across PDF parsers, making a single extraction method insufficient.
Chemical entities were reported inconsistently
The same material could appear under multiple names, formulas, abbreviations, or units, making direct record matching unreliable.
AI research results required chemical verification
Retrieved compounds needed additional validation before the system could include them in a research answer.
Scientific quality required domain expertise
Engineering validation alone could not determine whether every extracted record was scientifically correct.
Processing volume affected performance and cost
Parsing and analyzing large publication batches introduced additional compute requirements.
The infrastructure had to be created from scratch
Planck did not have an existing environment for this type of document and AI workload.
Multi-parser workflow
Our team combined several parsing approaches and created a separate workflow for scientific tables. Documents that still could not be processed reliably were flagged for review rather than discarded.
Chemical entity normalization
Geniusee introduced synonym mapping, standardized chemical identifiers, formula normalization, and unit conversion so different variants resolve into consistent entities and values.
Chemical result validation
The AI agent applies chemical validation and filtering to the retrieved results and removes duplicates before returning the final answer.
Expert review loop
Planck’s chemists reviewed representative samples throughout the project. Their corrections were converted into extraction rules, normalization logic, and test cases for subsequent sprints.
Scalable batch processing
The pipeline uses batching, parallel processing, caching, and incremental updates, so unchanged papers do not need to be processed repeatedly.
AWS infrastructure setup
Geniusee created the AWS infrastructure with Terraform, containerized the pipeline with Docker, introduced CI/CD, centralized monitoring, and autoscaling to align compute capacity with active workloads.